Advanced AI shouldn't need a data center.
Open research on making strong models run anywhere, with every tradeoff shown.
What we do
We shrink strong models and publish what happened.
We take open models and make them smaller and faster to run, then release the result with the full record: what worked, what broke, and what it cost.
01
Every tradeoff shown
Size, speed, and accuracy are published together, not cherry picked.
02
Numbers published even when bad
A failed run gets a number too, not a quiet rewrite.
03
Open weights
Weights are public to download, not a demo behind a form.
04
What broke goes in the record
Failed attempts are listed next to the one that worked.
How we work
Four methods. We mix and match.
Firn
Distillation
Train a small model to match a larger one.
Rime
Quantization
Store numbers with less precision.
Calve
Pruning
Remove the parts a model rarely uses.
Floe
Combined methods
Stack two or more of the above.
Releases
The log. Newest first.
-
FLOE-01
Floe series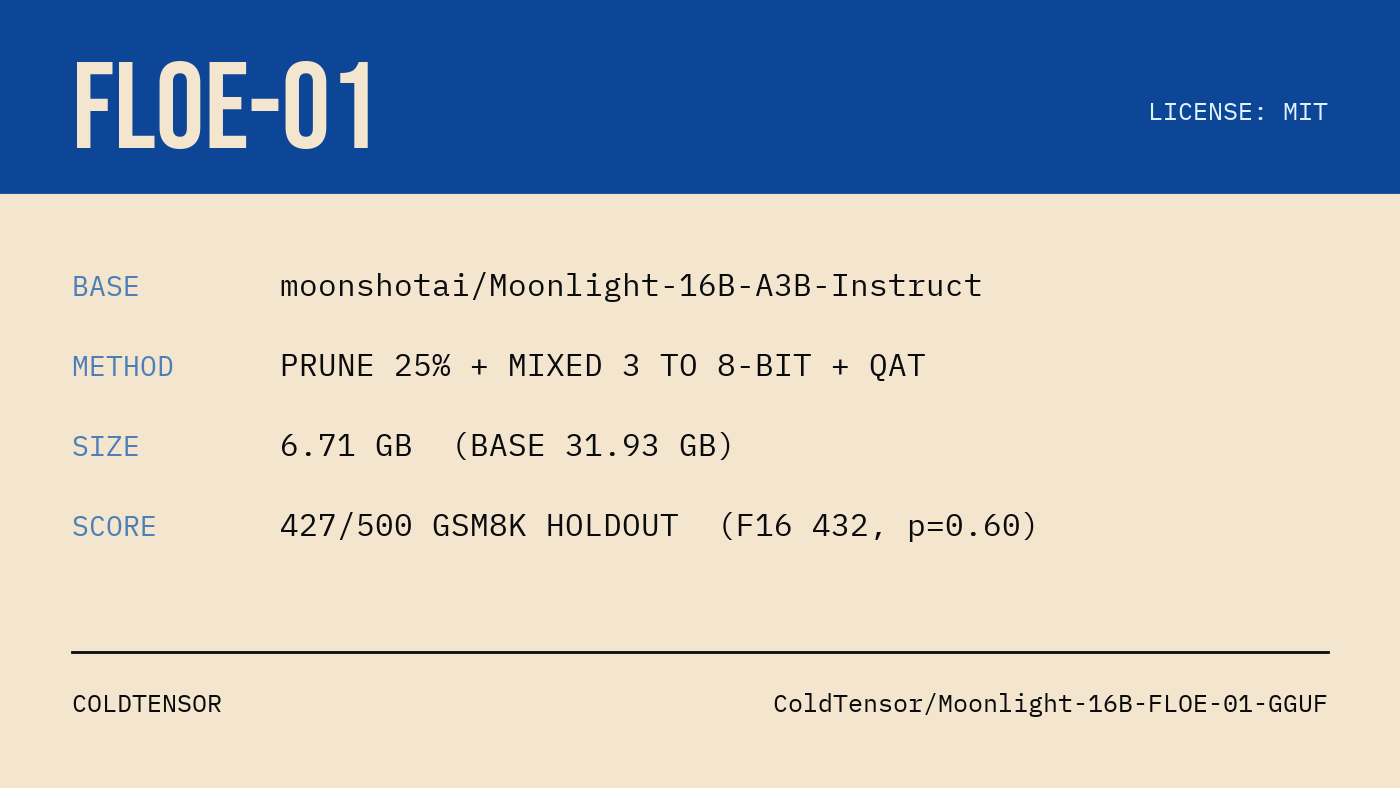
Base: Moonlight-16B-A3B-Instruct (Moonshot AI, MIT). Tested on one RTX PRO 6000 Blackwell.
A pruned, quantized, and briefly retrained copy of Moonlight-16B-A3B-Instruct.
6.7 GB
from about 32 GB.
427 / 500
on fresh held-out math problems. The original got 432.
Weak spot: coding. Lost all 3 coding prompts in a blind check.
More releases as they're ready.
"Advanced AI shouldn't need a data center. Open research on making strong models run anywhere, with every tradeoff shown."
FLOE-01 weights inherit the MIT license from the base model.